Find the path with YOLO, stay in the middle with RL
Two networks, each doing what it is good at. A YOLO segmentation model (Ultralytics) looks at the camera image and finds the path. A small reinforcement-learning policy looks only at that path mask and steers the Ackermann car so it stays in the middle of the ε track. The simulator makes the labelled training data itself.
1The goal
2Why two networks?
In tutorial 2 one network learned everything at once from raw pixels: what the track looks like and how to drive. Here the work is split:
- YOLO learns “where is the path?” That is supervised learning: thousands of images with the right answer. No trial and error, no reward.
- The policy learns “how do I steer?” That is reinforcement learning, but on a tiny, clean input: a black-and-white mask instead of a full image.
The big advantage shows when you move to a real robot. A real camera image looks very different from the simulator, but a path mask looks the same: so you can retrain only YOLO on real photos and keep the policy.
3What you need
As in tutorials 1 and 2 (the robotSimulatorAPI repository, Node.js 22+, Chrome, Python 3.10+), plus Ultralytics:
pip install ultralytics stable-baselines3 gymnasiumThe script is python/track_yolo.py; every step is one command:
node server.mjs                         # terminal 1: the simulators
python python/track_yolo.py dataset   # 1. images + labels        (~1 min)
python python/track_yolo.py yolo      # 2. train YOLO11n-seg      (~40 min CPU, minutes on a GPU)
python python/track_yolo.py rl        # 3. train the policy       (~10 min)
python python/track_yolo.py baseline
python python/track_yolo.py eval      # 4. a lap with YOLO in the loop
python python/track_yolo.py watch --gif lap.gif
Steps 2 and 3 don't depend on each other (the policy trains on the simulator's own masks), so you can run them at the same time in two terminals.
4Step 1 · a labelled dataset, made by the simulator
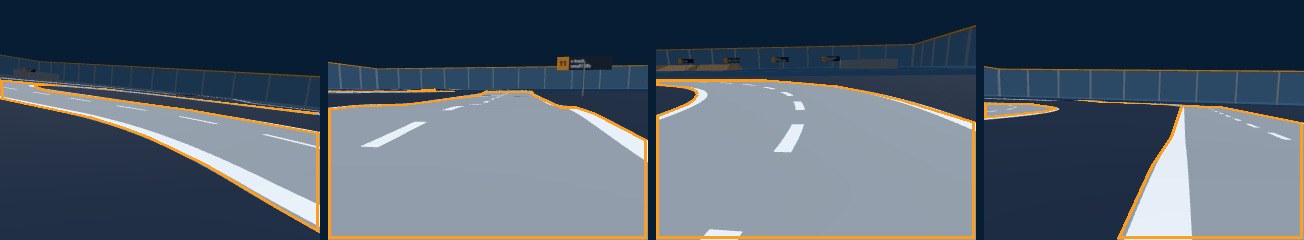
Labelling images by hand is the slow part of every segmentation project. Here the simulator knows exactly where
the path is, so it draws the label itself: next to the normal camera view (view: "robot") there is a
mask view (view: "mask") of the same camera, in which only the path is drawn, white on
black.
_, cam = api.reset(car, lane="track", start=s, offset=e, yaw=a,          # somewhere on the track
                   image={"view": "robot", "width": 320})        # the camera image (JPEG)
mask = api.frame(car, view="mask", width=320) # the label (PNG)- Every view a driving robot gets: a random spot on the track, up to 55 cm beside the centre line and turned up to ±50°, so YOLO also sees the path from the edge and at an angle.
- Three robots: mostly the Ackermann's camera, plus the skid steer and 4WD (their camera sits at another height).
- From mask to YOLO label: OpenCV finds the outline of the white area; every outline becomes one line
0 x1 y1 x2 y2 …(class 0 = “path”, coordinates 0 … 1). Ultralytics reads that format directly.
track_data/
  images/train/train_00000_ackermann.jpg   …   labels/train/train_00000_ackermann.txt
  images/val/…                                 labels/val/…
track.yaml # path, train, val, names: {0: path}5Step 2 · train YOLO11n-seg
We start from yolo11n-seg.pt, the smallest YOLO11 segmentation model (2.9 million weights), already
trained on the COCO photo set: it knows edges and shapes, and only has to learn what our path looks like
(transfer learning).
model = YOLO("yolo11n-seg.pt")
model.train(data="track_data/track.yaml", imgsz=320, epochs=30, batch=16,
project=os.path.abspath("runs/segment"), name="track")best.pt.| Precision | Recall | mAP50 | mAP50-95 | |
|---|---|---|---|---|
| Mask | 0.91 | 0.82 | 0.89 | 0.80 |
| Box | 0.95 | 0.86 | 0.96 | 0.83 |
mAP50 counts a found path as right when it overlaps the label for at least 50 %; mAP50-95 averages over stricter thresholds up to 95 %, so it also rewards exact edges.
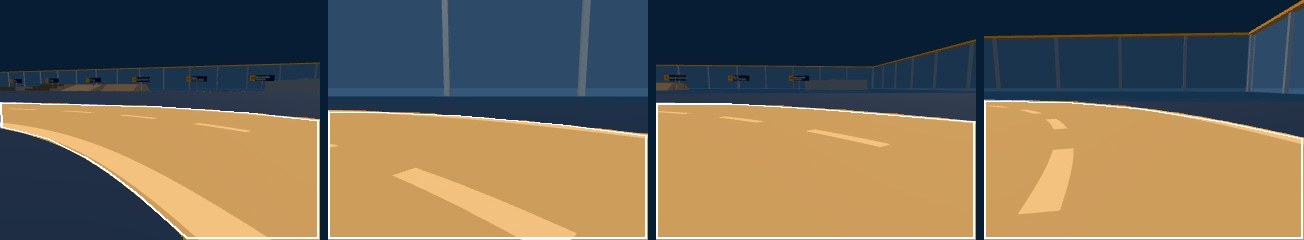
Ultralytics normally saves into the runs_dir of its own settings, which may be a
folder of another project. The script passes an absolute project folder, so the run lands in
runs/segment/track next to where you run the command.
6Step 3 · RL: stay in the middle
Observation: a path mask
64 × 48, white = path, the last two stacked (so it sees which way the path moves). In training the mask comes straight from the simulator's mask view: 0.3 ms instead of 15 ms for YOLO, so training is about 50× cheaper per image.
Imperfect on purpose
YOLO's masks will never be perfect, so the training masks get YOLO-like flaws: the edge shifted by a pixel, 2 % of the pixels flipped, and now and then a missing chunk. A policy that never saw a flawed mask can panic at the first one.
def noisy(mask, rng):
    m = mask > 127
    if rng.random() < 0.5:                            # ragged edge: shrink or grow one pixel
        shift = np.roll(m, rng.choice([-1, 1]), axis=rng.integers(0, 2))
        m = m & shift if rng.random() < 0.5 else m | shift
    m ^= rng.random(m.shape) < 0.02                     # speckles
    if rng.random() < 0.15:                           # a missing chunk
        y, x = rng.integers(0, MH - 8), rng.integers(0, MW - 12)
        m[y:y + 8, x:x + 12] = False
    return m.astype(np.uint8) * 255
Action and reward
The policy only steers; the throttle is fixed at 60 %: this tutorial is about staying in the middle, not about speed. Per step (0.1 s):
e = offset / 0.35                    # 0 in the middle, ±1 at the edge of the path
reward = 1 − e²                      # 1 in the exact middle, 0 at the edge
reward = −10, attempt over           # when it leaves the path
Attempts start at a random spot, up to 20 cm beside the centre line and turned up to ±20°: it has to learn to come back to the middle, not only to stay there.
python python/track_yolo.py rl
Saved track_middle_ppo.zip after 11.1 min| Steps | ep_len_mean (max 300) | reward per step | What is happening |
|---|---|---|---|
| 10 000 | 54 | 0.60 | leaves the path after a few seconds |
| 25 000 | 138 | 0.80 | takes most bends |
| 50 000 | 252 | 0.87 | rarely leaves the path |
| 150 000 | 294 | 0.94 | close to the middle almost all the time |
7Step 4 · YOLO in the loop
Now the real test: camera image → YOLO → mask → policy → steering, a whole lap from the chequered line.
python python/track_yolo.py baseline
python python/track_yolo.py eval --masks sim     # the simulator's perfect masks
python python/track_yolo.py eval # masks from YOLO| Driver | Lap | From the middle: mean | max | Left the path |
|---|---|---|---|---|
| Line follower that knows its exact offset (gains tuned) | 76.5 s | 2.5 cm | 6.2 cm | 0 |
| PPO, perfect masks from the simulator | 73.7 s | 4.3 cm | 19.0 cm | 0 |
| PPO, masks from YOLO | 74.0 s | 3.8 cm | 17.3 cm | 0 |
Two things stand out. The policy steers as well with YOLO's masks as with perfect ones (even a bit better: YOLO's edges are smooth, and the policy was trained on flawed masks). And a line follower that is told its exact position still stays closer to the middle: the policy has to estimate it from a 64 × 48 mask, where one pixel is a few centimetres. Its largest deviations are in the sharp bends, where it cuts the corner a little (its lap is also shorter).
YOLO took 15 ms per image on the laptop's CPU: fast enough for ten decisions a second.
8An experiment with the reward
With 1 − e² a small deviation costs almost nothing (4 cm off: 0.013). Would a reward that pulls harder
near the middle, 1 − |e|, keep it more centred? We trained it to find out:
python python/track_yolo.py rl --reward linear --policy middle_linear.zip| Reward | Perfect masks: mean / max | YOLO masks: mean / max |
|---|---|---|
1 − e² (default) | 4.3 / 19.0 cm | 3.8 / 17.3 cm |
1 − |e| | 5.0 / 16.5 cm | 5.4 / 19.2 cm |
Not better. So the reward was not what limited it, the observation was: a coarse mask can't show a few centimetres. That is a typical RL lesson: before tuning the reward, ask what the agent can actually see.
9Towards a real robot
- Make a path on the floor (tape, paper, paint) and put a camera on your robot, about where the simulator's is.
- Take a few hundred photos while driving, label the path (or let YOLO pre-label them and correct), and
fine-tune
runs/segment/track/weights/best.pton simulator + real images together. - Keep the policy as it is: it only sees masks.
- Export YOLO for the robot's computer, for example
yolo export model=best.pt format=onnx imgsz=320(ortflitefor a small board), and send the steering to the motors as in the simulator.
10Experiments
| Try | How | What to look for |
|---|---|---|
| Less data | dataset --images 300 | How few images does YOLO need on this track? |
| Fewer epochs | yolo --epochs 10 | Does a weaker mask make the car steer worse? |
| No noise in training | let noisy() return the mask unchanged | Does it still drive well on YOLO masks? |
| Another robot | --robot skid or 4wd | YOLO saw those cameras; does the policy carry over? |
| Faster | THROTTLE = 0.9 | Can it still stay in the middle at speed? |
Challenge: beat the line follower's 2.5 cm with YOLO in the loop. Hint: give the policy a bigger mask, or crop away the sky before shrinking it.
11Troubleshooting
| Problem | Solution |
|---|---|
ConnectionRefusedError | Start node server.mjs first and leave it running. |
| YOLO results end up in another folder | An older version of the script followed Ultralytics' own runs_dir; the current one saves next to where you run it. Check with yolo settings. |
eval can't find best.pt | Run eval from the folder where you trained, or pass --yolo path/to/best.pt. |
| YOLO training is slow | On a GPU: yolo --device 0 (needs the CUDA build of PyTorch, see tutorial 2). |
The car leaves the path with YOLO but not with --masks sim | YOLO misses part of the path: train it longer or with more images; look at runs/segment/track/val_batch*_pred.jpg. |